2.5. SPARTA
This is the documentation for the benchmark [SPARTA]. The content herein was created by the following authors (in alphabetical order).
This material is based upon work supported by the Sandia National Laboratories (SNL), a multimission laboratory managed and operated by National Technology and Engineering Solutions of Sandia under the U.S. Department of Energy’s National Nuclear Security Administration under contract DE-NA0003525. Content herein considered unclassified with unlimited distribution under SAND2023-01070O.
2.5.1. Purpose
Heavily pulled from their [site]:
SPARTA is an acronym for Stochastic PArallel Rarefied-gas Time-accurate Analyzer. SPARTA is a parallel Direct Simulation Monte Carlo (DSMC) code for performing simulations of low-density gases in 2d or 3d. Particles advect through a hierarchical Cartesian grid that overlays the simulation box. The grid is used to group particles by grid cell for purposes of performing collisions and chemistry. Physical objects with triangulated surfaces can be embedded in the grid, creating cut and split grid cells. The grid is also used to efficiently find particle/surface collisions. SPARTA runs on single processors or in parallel using message-passing techniques and a spatial-decomposition of the simulation domain. The code is designed to be easy to modify or extend with new functionality. Running SPARTA and the input command syntax is very similar to the LAMMPS molecular dynamics code (but SPARTA and LAMMPS use different underlying algorithms).
2.5.2. Problems
The goal is to utilize the specified version of SPARTA (see Application Version) that runs the benchmark problem (see Problems) correctly (see Validation if changes are made to SPARTA).
This input sets up a SPARTA simulation of argon gas particles moving through a 3-D box. The particles collide with each other using a gas-physics collision model, so it represents collisional flow rather than free molecular flow. The gas starts at a temperature of 273.15 K with no overall flow velocity.
This benchmark is relevant to production because it exercises the main costs of a DSMC simulation: particle movement, particle sorting into cells, and particle collisions. It has good weak-scaling characteristics, so it is useful for testing how well SPARTA performs as the problem size and processor count grow on large supercomputers. Although it has no surfaces, that still represents important production-style physics problems, such as Taylor–Green turbulent flow or Rayleigh–Taylor mixing, where the dominant work is in the gas-particle dynamics rather than surface interactions. Surface-heavy problems are often harder to use as clean benchmarks because load imbalance can grow as processor domains get smaller, making it difficult to separate algorithmic performance from geometry-induced imbalance.
This problem models 2D hypersonic flow of nitrogen over a circle with periodic boundary conditions in the z dimension, which physically translates to 3D flow over a cylinder of infinite length. Particles are continuously emitted from the 4 faces of the simulation box during the simulation, bounce off the circle, and then exit. The hierarchical cartesian grid is statically adapted to 6 levels around the circle. The memory array used to hold particles is reordered by grid cell every 100 timesteps to improve data locality and cache access patterns.
This problem is a modified version of an existing benchmark problem within the SPARTA repository. Adding it formally is being actively discussed. The components of this problem are listed below (paths given are within SPARTA repository). Each of these files will need to be copied into a run directory for the simulation.
in.collide_halt_balanceThis is the default input file that controls the simulation. Some parameters within this file may need to be changed depending upon what is being run (e.g., these parameters control how much memory it uses).
An excerpt from this input file that has its key parameters is provided below.
# advect particles via VSS collisional flow on a uniform grid
# particles reflect off global box boundaries
#
# Balanced weak-scaling version.
#
# Assumptions:
#   nscale = number of nodes
#   4 MPI ranks / GPUs per node
#   total MPI ranks = 4*nscale
#   nscale must be a power of 2
#
# Goal:
#   Every MPI rank owns a cubic local grid:
#     nloc x nloc x nloc
#
# The global domain may be non-cubic.

variable            nscale index 1
variable            ppc index 10

global              optmove yes particle/reorder 10
# Help debug slow nodes...
# global              timer/rank yes timer/file timings.txt

# -------------------------------------------------------------------------
# Local grid size per MPI rank
#
# 305^3 = 28,372,625 cells/rank
# with ppc=10 -> 283,726,250 particles/rank
# -------------------------------------------------------------------------

variable            nloc index 305
<snip>
stats_style         step cpu spcpu np nattempt ncoll
stats               10
stats_modify        flush yes
<snip>
timestep            7.00E-8
run                 30
<snip>
###################################
# Output
###################################

stats               0

# Stop after 5.5 minutes
fix             1 halt 10 tlimit > 330.0 message no error continue
run             1000000

unfix           1
reset_timestep 0

# Stop after 5.5 minutes
fix             2 halt 10 tlimit > 330.0 message no
run             1000000

These parameters are described below.
nlocThis corresponds to the length scale factor. This will scale the x and y dimensions of the problem, e.g., a doubling of this parameter will result in a domain that is 4x larger. This is used to weak scale a problem, e.g., setting this to 32 would be sufficient to weak scale a single-node problem onto 1,024 nodes.
nscaleThis sets the particles per cell variable. This variable controls the size of the problem and, accordingly, the amount of memory it uses. Adjust this if the initial memory size is too high and a value of
Lwould need to be less than 1.0.statsThis sets the interval at which the output required to compute the Figure of Merit is generated. In general, it is good to select a value that will produce approx. 20 entries between the time range of interest. If it produces too much data, then it may slow down the simulaton. If it produces too little, then it may adversely impact the FOM calculations.
stats_modify flush yesThis enables the log output to buffer continuously on El Capitan.
run 30This sets the first sub-job to run for 30 steps at a large timestep to unsort the particle array.
fix 1 halt 10 tlimit > 330.0 message no error continueThis sets the second sub-job termination to 330.0 seconds of wall time by checking on progress up to every 10 steps. This is the transient period whose performance will be discarded.
fix 2 halt 10 tlimit > 330.0 message noThis sets the third sub-job termination to 330.0 seconds of wall time by checking on progress up to every 10 steps. This is the period whose performance will be evaluated. The simulation will stop afterwards.
Note
First, one scales the problem size on a single node to match the
needed memory characteristics via nloc. Then, one weak scales
from a single node to an arbitrary number by changing
nscale. Both of these parameters are defined via index, so
they can be altered on the command line invocation of SPARTA.
Due to differences in how memory is allocated, Kokkos must be enabled for the simulation regardless of the hardware being used. If Kokkos is enabled, the following excerpts should be found within the log file.
SPARTA (dd mmm yyyy)
KOKKOS mode is enabled (/path/to/kokkos.cpp:40)
  requested 1 GPU(s) per node
  requested 1 thread(s) per MPI task
Running on 4 MPI task(s)
package kokkos
2.5.2.1. Figure of Merit
Each SPARTA simulation writes out a file named “log.sparta”. At the end of this simulation is a block that resembles the following example.
    Step          CPU        S/CPU         Np      Natt     Ncoll
       0            0            0 9079240000 903884280 641603306
     200    24.009253    8.3301203 9079240000 903879874 641591530
Loop time of 24.3716 on 32 procs for 200 steps with 9079240000 particles
Performance: 8.206 timesteps/s, 74.507 Gparticle-step/s
The Figure of Merit (FOM) is “Gparticle-step/s”, which can be directly extracted from the last line of the 3rd sub-job’s performance output (which resembles the block above). Sometimes it is useful to normalize the FOM by the number of nodes. The ultimate goal is to maximize this throughput FOM while utilizing at least 50% of available memory.
2.5.3. Source code modifications
Please see Run Rules Synopsis for general guidance on allowed modifications. For SPARTA, source code modifications should satisfy the correctness criteria in Validation when changes are made to SPARTA.
2.5.4. System Information
The platforms utilized for benchmarking activities are listed and described below.
Advanced Technology System 4 (ATS-4), also known as El Capitan (see El Capitan)
Commodity Technology System 2 (CTS-2) with 4x Nvidia H100 GPUs, also known as Hops.
2.5.5. Building
2.5.5.1. Application Version
The command to clone is provided below.
git clone --branch 27Aug2026 git@github.com:sparta/sparta.git
Note
This version of SPARTA has been updated to include the full inclusion of Kokkos 5 and the CMake build along with at-scale performance enhancements.
The script to clone can be downloaded from sparta_clone.sh. It can also be executed in place to clone into
docs/31_sparta/sparta.
cd docs/31_sparta
./sparta_clone.sh
A script (sparta_clone.sh) is provided to clone the SPARTA
repository within the “sparta” folder. Instructions are provided on
how to build SPARTA for the following systems:
Generic (see Generic)
Advanced Technology System 4 (ATS-4), also known as El Capitan (see El Capitan)
Commodity Technology System 2 (CTS-2) with 4x Nvidia H100 GPUs, also known as Hops (see Hops)
2.5.5.2. Generic
Refer to SPARTA’s [sparta-build] documentation for generic instructions.
2.5.5.3. El Capitan
Instructions for building on El Capitan are provided below. These instructions assume this repository has been cloned and that the current working directory is at the top level of this repository.
cd docs/31_sparta
./sparta_build_elcapitan.sh
The script discussed above is sparta_build_elcapitan.sh and is produced below for convenience and
reference.
#!/usr/bin/env bash

# set top-level script parameters
umask 022
set -e
set -x

# create vars for common directories and files
dir_root="`git rev-parse --show-toplevel`"
dir_pwd="` pwd -P `"
dir_src="${dir_pwd}/sparta"
dir_build="${dir_pwd}/sparta/_build"
file_log="${dir_pwd}/sparta_build.log"

# redirect STDOUT and STDERR through tee
exec &> >(tee >(ts '[%Y-%m-%d %H:%M:%S]' > "${file_log}"))

# let's turn on verbosity now
set -v

# output for posterity
hostname
uptime
lscpu

# clean and reset source
pushd "${dir_src}"
git clean -fdx
git reset --hard
popd

# create build directory
test -d "${dir_build}" && rm -rf "${dir_build}"
mkdir -p "${dir_build}"

# build
#   list current environment
module list
#   alter environment
. sparta_env_elcapitan.sh
#   list current environment
module list
pushd "${dir_build}"
cmake \
    -C ../cmake/presets/elcapitan_kokkos.cmake \
    -D SPARTA_DEFAULT_CXX_COMPILE_FLAGS="-DSPARTA_BIGBIG" \
    -D BUILD_MPI=on \
    ../cmake
/usr/bin/time --verbose -- \
    nice -n 1 \
        gmake -j 64
popd

# gracefully exit
exit 0
2.5.5.4. Hops
Instructions for building on Hops are provided below. These instructions assume this repository has been cloned and that the current working directory is at the top level of this repository.
cd docs/31_sparta
./sparta_build_hops.sh
The script discussed above is sparta_build_hops.sh and is produced below for convenience and
reference.
#!/usr/bin/env bash

# set top-level script parameters
umask 022
set -e
set -x

# create vars for common directories and files
dir_root="`git rev-parse --show-toplevel`"
dir_pwd="` pwd -P `"
dir_src="${dir_pwd}/sparta"
dir_build="${dir_pwd}/sparta/_build"
file_log="${dir_pwd}/sparta_build.log"

# redirect STDOUT and STDERR through tee
exec &> >(tee >(ts '[%Y-%m-%d %H:%M:%S]' > "${file_log}"))

# let's turn on verbosity now
set -v

# output for posterity
hostname
uptime
lscpu

# clean and reset source
pushd "${dir_src}"
git clean -fdx
git reset --hard
popd

# create build directory
test -d "${dir_build}" && rm -rf "${dir_build}"
mkdir -p "${dir_build}"

# build
#   list current environment
module list
#   alter environment
. sparta_env_hops.sh
#   list current environment
module list
pushd "${dir_build}"
cmake \
    -C ../cmake/presets/kokkos_cuda.cmake \
    -D SPARTA_DEFAULT_CXX_COMPILE_FLAGS="-DSPARTA_BIGBIG" \
    -D BUILD_MPI=on \
    ../cmake
/usr/bin/time --verbose -- \
    nice -n 1 \
        gmake -j 64
popd

# gracefully exit
exit 0
2.5.6. Running
Instructions are provided on how to run SPARTA for the following systems:
Advanced Technology System 4 (ATS-4), also known as El Capitan (see El Capitan) * Profiling with Kokkos Tools on El Capitan (see Profiling with Kokkos Tools)
Commodity Technology System 2 (CTS-2) with 4x Nvidia H100 GPUs, also known as Hops (see Hops) * Profiling with Kokkos Tools on Hops (see Profiling with Kokkos Tools)
2.5.6.1. El Capitan
An example for performing simulations on El Capitan is provided below.
# first, copy templatedir into something useful
cp -a templatedir useful

# next, go into the run folder
cd useful

# submit job and set parameters on command line if desired
#   this example sets nloc (aka sparta_nloc) to 355
#   this example turns on Kokkos Tools profiling (aka kokkos_tools)
#   this example runs on 1 node (aka --nodes=1)
sparta_nloc=355 is_kokkos_tools=1 flux batch --nodes=1 sparta_batch_elcapitan.sh
2.5.6.1.1. Profiling with Kokkos Tools
Scripts are provided to clone and build Kokkos Tools. The steps to do both are provided below.
# go into the SPARTA documentation folder
cd docs/31_sparta

# clone Kokkos Tools
./kokkos_tools_clone.sh

# build Kokkos Tools' Space Time
./kokkos_tools_build_elcapitan.sh
Once built, the command line variable is_kokkos_tools can be set
to 1 for the batch script to turn it on. After a successful run,
it will output additional memory information. An example of this (for
L equal to 2.0 and ppc equal to 47) on El Capitan is provided
below that shows approximately 82.2 GB of memory allocated on each
GPU.
KOKKOS HIP SPACE:
===================
MAX MEMORY ALLOCATED: 82222221.9 kB
2.5.6.2. Hops
An example for performing simulations on Hops is provided below.
# first, copy templatedir into something useful
cp -a templatedir useful

# next, go into the run folder
cd useful

# submit job and set parameters on command line if desired
#   this example sets nloc (aka sparta_nloc) to 355
#   this example turns on Kokkos Tools profiling (aka kokkos_tools)
#   this example runs on 1 node (aka --nodes=1)
sparta_nloc=355 is_kokkos_tools=1 sbatch --nodes=1 sparta_batch_hops.sh
2.5.6.2.1. Profiling with Kokkos Tools
Scripts are provided to clone and build Kokkos Tools. The steps to do both are provided below.
# go into the SPARTA documentation folder
cd docs/31_sparta

# clone Kokkos Tools
./kokkos_tools_clone.sh

# build Kokkos Tools' Space Time
./kokkos_tools_build_hops.sh
Once built, the command line variable is_kokkos_tools can be set
to 1 for the batch script to turn it on. After a successful run,
it will output additional memory information. An example of this (for
L equal to 2.0 and ppc equal to 47) on El Capitan is provided
below that shows approximately 82.2 GB of memory allocated on each
GPU.
KOKKOS CUDA SPACE:
===================
MAX MEMORY ALLOCATED: 82222221.9 kB
2.5.7. Validation
The aforementioned relevant block of output within “log.sparta” is replicated below.
    Step          CPU        S/CPU         Np      Natt     Ncoll
       0            0            0 9079240000 903884280 641603306
     200    24.009253    8.3301203 9079240000 903879874 641591530
Loop time of 24.3716 on 32 procs for 200 steps with 9079240000 particles
Performance: 8.206 timesteps/s, 74.507 Gparticle-step/s
There are several columns of interest regarding correctness; these are listed below.
StepThis is the step number and is the first column.
CPUThis is the elapsed time and is the second column.
S/CPUThis is the number of steps per CPU. It is a simulation rate that allows one to view relative performance across different output steps.
NpThis is the number of particles and is the third column.
NattThis is the number of attempts and is the fourth column.
NcollThis is the number of collisions and is the fifth column.
Assessing the correctness will involve comparing these quantities across modified (henceforth denoted with “mod” subscript) and unmodified (“unmod” subscript) SPARTA subject to the methodology below.
The first step is to adjust the run input file parameter so
that SPARTAmod has CPU output that exceeds 600 seconds
(per Figure of Merit). Also, adjust the stats parameter
to a value of 1 so fine-grained output is generated; if this is
significantly slowing down computation, then it can be increased to a
value of 10. Then, produce output from SPARTAunmod with the
same run and stats settings.
The second step is to compute the absolute differences between
modified and unmodified SPARTA for Np, Natt, and Ncoll for
each row, i, whose Step is relevant for the FOM for SPARTAmod,
where
i is each line whose
CPUtime is between 300 and 600 seconds for SPARTAmod
The third step is to compute the arithmetic mean of each of the aforementioned quantities over the n rows,
where
The fourth step is to compute the arithmetic mean of the n matching rows of the unmodified SPARTA,
The fifth step is to normalize the differences with the baseline values to create the error ratios,
The sixth and final step is to check over all of the error ratios and if any of them exceed 25%, then the modifications are not approved without discussing them with this benchmark’s authors. This is the same criteria that SPARTA uses for its own testing. The success criteria are:
2.5.8. Memory Usage
SPARTA memory usage depends on the selected problem size and on the Kokkos backend used for a given system. Memory-usage guidance is currently captured through the Kokkos Tools profiling instructions for El Capitan and Hops in Profiling with Kokkos Tools and Profiling with Kokkos Tools.
2.5.9. Baseline on El Capitan
SPARTA weak scaling performance on El Capitan (AMD Epyc + AMD MI300A) is provided as follows.
2.5.9.1. Compute Figure of Merit
As stated in Figure of Merit, the FOM is the QOI directly extracted from the SPARTA log file divided by the number of nodes.
2.5.9.2. El Capitan - Single Node
Note
This data is forthcoming.
2.5.9.3. El Capitan - Many Nodes
The weak-scaling data are provided in
elcapitan-weakscaling.csv.
Nodes |
FOM (Gparticle-step/s) |
FOM/node (Gparticle-step/s/node) |
Parallel Efficiency |
|---|---|---|---|
1 |
8.95167051 |
8.95167051 |
1.0 |
8 |
67.5600477 |
8.44500596 |
0.9434 |
64 |
526.845197 |
8.2319562 |
0.9196 |
512 |
4198.26186 |
8.19973019 |
0.916 |
4096 |
32500.78 |
7.93476074 |
0.8864 |
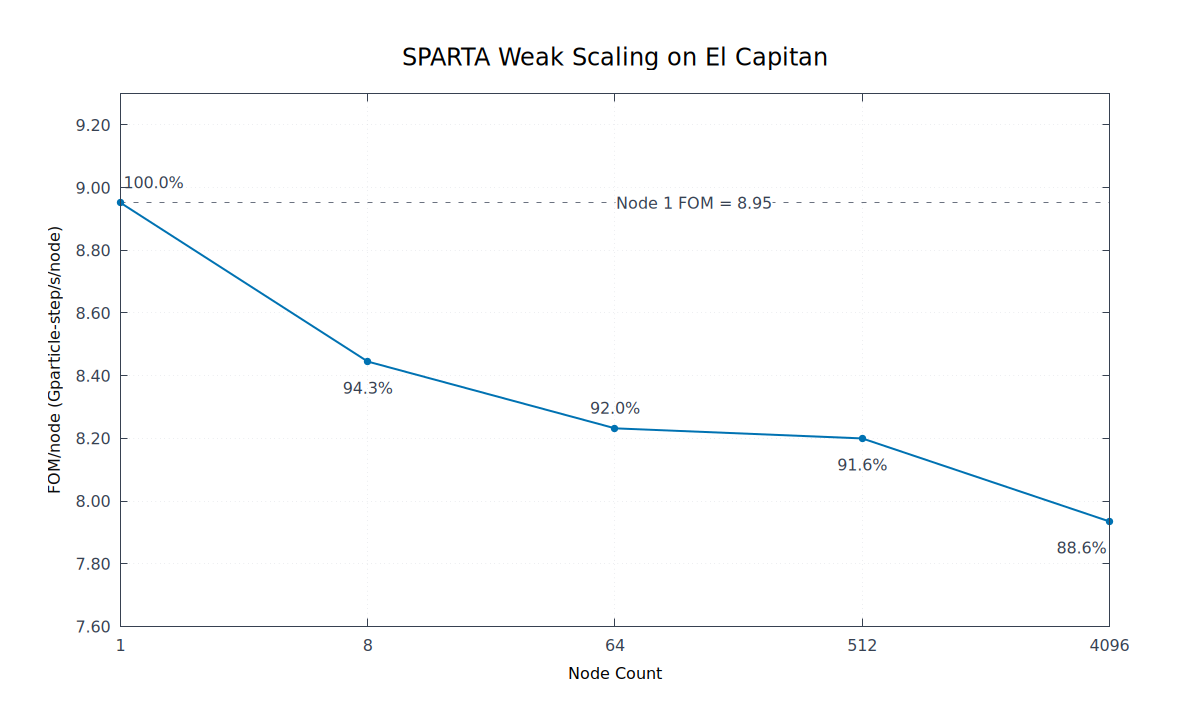
Fig. 2.5 SPARTA weak-scaling Figure of Merit on El Capitan. Point annotations show the corresponding parallel efficiency at each node count.
2.5.9.4. Results on Hops
SPARTA performance data on Hops (CTS-2 with Nvidia H100 GPUs) is provided as follows.
2.5.9.5. Hops - Single Node
Note
This data is forthcoming.
2.5.9.6. Hops - Many Nodes
Note
This data is forthcoming.
2.5.10. Performance Projection
Use the system-specific memory guidance and baseline weak-scaling results above to select SPARTA problem sizes that use the available node memory while completing the benchmark run successfully. The El Capitan results can be used to project ATS-4 scalable-unit performance; analogous Hops data can be used for CTS-2+GPU projections once available.
2.5.11. References
S. J. Plimpton and S. G. Moore and A. Borner and A. K. Stagg and T. P. Koehler and J. R. Torczynski and M. A. Gallis, ‘Direct Simulation Monte Carlo on petaflop supercomputers and beyond’, 2019, Physics of Fluids, 31, 086101.
M. Gallis and S. Plimpton and S. Moore, ‘SPARTA Direct Simulation Monte Carlo Simulator’, 2023. [Online]. Available: https://sparta.github.io. [Accessed: 22- Feb- 2023]
M. Gallis and S. Plimpton and S. Moore, ‘SPARTA Documentation Getting Started’, 2023. [Online]. Available: https://sparta.github.io/doc/Section_start.html#start_2. [Accessed: 26- Mar- 2023]