2.1. Kripke
https://github.com/LLNL/Kripke
2.1.1. Purpose
Kripke is a scalable 3D Sn deterministic particle transport code. Its primary purpose is to research how data layout, programming paradigms and architectures affect the implementation and performance of Sn transport. A main goal of Kripke is to investigate how different data-layouts affect instruction, thread, and task level parallelism, and the implications on overall solver performance.
Kripke supports storage of angular fluxes (Psi) using all six striding orders (or “nestings”) of Directions (D), Groups (G), and Zones (Z), and provides computational kernels specifically written for each of these nestings. Most Sn transport codes are designed around one of these nestings, which is an inflexibility that leads to software engineering compromises when porting to new architectures and programming paradigms.
Early research has found that the problem dimensions (zones, groups, directions, scattering order) and the scaling (number of threads and MPI tasks), can make a profound difference in the performance of each of these nestings. To our knowledge, this is a capability unique to Kripke, and should provide key insight into how data-layout affects Sn solver performance. An asynchronous MPI-based parallel sweep algorithm is provided, which employs the concepts of Group Sets (GS), Zone Sets (ZS), and Direction Sets (DS), borrowed from the [Texas A&M code PDT](https://multiphysics.engr.tamu.edu/research-topics/parallel-deterministic-transport/).
As we explore new architectures and programming paradigms with Kripke, we will be able to incorporate these findings and ideas into our larger codes. The main advantages of using Kripke for this exploration is that it’s light-weight (i.e. easily refactored and modified), and it gets us closer to the real question we want answered: “What is the best way to layout and traverse data in parallel in an Sn code on a given architecture+programming-model?” instead of the more commonly asked question “What is the best way to map my existing Sn code to a given architecture+programming-model?”.
2.1.2. Problems
The problem of interest for Kripke will be run with 48 energy groups, 80 angles, and a range of zones that are TBD. The problem will be run with a GDZ loop ordering, which means the kernels will run the dimensions of the problem in the following order from the outer-most to the inner-most loop: energy groups, directions (angles), and zones.
2.1.3. Figure of Merit
The figure of merit (FOM) is the grind time generated from the Kripke output. It measures the amount of time required per iteration to solve each unknown.
2.1.4. Source code modifications
Please see Run Rules Synopsis for general guidance on allowed modifications. For Kripke, we define the following restrictions on source code modifications:
Kripke must use RAJA as the portability library, available at https://github.com/LLNL/RAJA . While source code changes to RAJA can be proposed, RAJA and its dependencies in Kripke may not be removed or replaced with any other library.
Kripke must use Umpire, a portable memory management library that provides memory allocation, pooling, and data transfers across CPU and GPU memory spaces, available at https://github.com/llnl/Umpire . While source code changes to Umpire can be proposed, Umpire and its dependencies in Kripke may not be removed or replaced with any other library.
Kripke should use CHAI as a copy-hiding array abstraction to automatically migrate data between memory spaces. CHAI is available at https://github.com/llnl/chai .
Changes cannot be made to the loop ordering defined in the problem, i.e. GDZ must stay the same. However, tiling and other loop optimizations can be made provided that the loop ordering of GDZ remains unchanged.
Although the problem of interest requires 48 energy groups, and 80 angles, these values cannot be assumed to be constant. Compiler or code optimizations targeted at these values are not allowed.
2.1.5. Building
The easiest way to get Kripke running, is to directly invoke CMake and take whatever system defaults you have for compilers and let CMake find MPI for you.
Step 1: Create a build space (assuming you are starting in the Kripke root directory)
mkdir build
Step 2: Run CMake in that build space
cd build cmake ..
Load the particular compilation module suited for your system. On a system like El Capitan, load the following module:
module load rocmcc/6.4.3-cce-20.0.2-magic
For a number of platforms, we have CMake cache files that make things easier:
cd build cmake .. -C ../host-configs/llnl-toss4-MI300A-rocm6-adams.cmake -DCMAKE_BUILD_TYPE=Release
Step 3: Now make Kripke:
make -j8
GPU-aware MPI build options:
The CMake host-config files contain Kripke’s standard combinations of build options.
ENABLE_MPIis turned on in nearly all of the host configurations, and the following are additional MPI-related options.ENABLE_GPU_AWARE_MPI: Enable MPI communication directly using GPU buffers. Requires MPI support, either CUDA or HIP support, and an MPI installation that accepts device buffers.ENABLE_DIRECT_UMPIRE_PLANE_STORAGE: Allocate the three communication plane-field arrays (i,j, andk) separately from the primary Umpire memory pool. This may help optimize GPU-aware MPI buffering. RequiresENABLE_GPU_AWARE_MPI=ON.
2.1.6. Running
On a system similar to El Capitan (Cray system with AMD CPUs and MI300A GPUs), the following environment variable needs to be set:
export MPICH_GPU_SUPPORT_ENABLED=1
Furthermore on a system similar to El Capitan, one of the following environment variables should be set if ENABLE_GPU_AWARE_MPI and/or ENABLE_DIRECT_UMPIRE_PLANE_STORAGE are on. Either of these may improve GPU-aware MPI performance, depending on the system being used:
export MPICH_NOLOCAL=1
export MPICH_GPU_IPC_CACHE_MAX_SIZE=1000
Run Kripke with the desired problem parameters by doing:
/path/to/kripke.exe –layout GDZ –groups 48 –quad 80
2.1.7. Validation
At the end of each iteration in Kripke, a particle count is produced, along with an associated change in particle count. See the example Kripke output:
Steady State Solve
iter 0: particle count=5.499225e+07, change=1.000000e+00
iter 1: particle count=8.223750e+07, change=3.312996e-01
iter 2: particle count=9.569370e+07, change=1.406174e-01
iter 3: particle count=1.023260e+08, change=6.481557e-02
iter 4: particle count=1.055884e+08, change=3.089706e-02
iter 5: particle count=1.071896e+08, change=1.493820e-02
iter 6: particle count=1.079737e+08, change=7.261910e-03
iter 7: particle count=1.083568e+08, change=3.535318e-03
iter 8: particle count=1.085435e+08, change=1.720397e-03
iter 9: particle count=1.086344e+08, change=8.361880e-04
Solver terminated
The CPU results of the per-iteration particle count and change are treated as the ground truth, correct answers. To obtain the correct answers for a problem configuration, simply run Kripke with the inputs desired on a CPU system. Particle counts and change on the proposed system must match the CPU-generated particle counts and change for every iteration, provided that the same Kripke input parameters are used in both the proposed system run and the CPU-generated run.
2.1.8. Memory Usage
Kripke uses CHAI and Umpire to manage GPU memory. During initialization, it
calculates the memory required for the selected problem size and preallocates
an Umpire device-memory pool accordingly. The --dev_pool_size runtime
parameter can be used to override the calculated pool size. Its value is an
integer number of gigabytes per rank.
When Kripke is configured with
-DENABLE_DIRECT_UMPIRE_PLANE_STORAGE=ON, it allocates the three plane-field
arrays (i, j, and k) in a separate Umpire GPU memory allocation, instead of from the
primary Umpire pool. This optimization can improve performance for smaller problem
sizes and is disabled by default, and requires GPU-aware MPI to be enabled via -DENABLE_GPU_AWARE_MPI=ON.
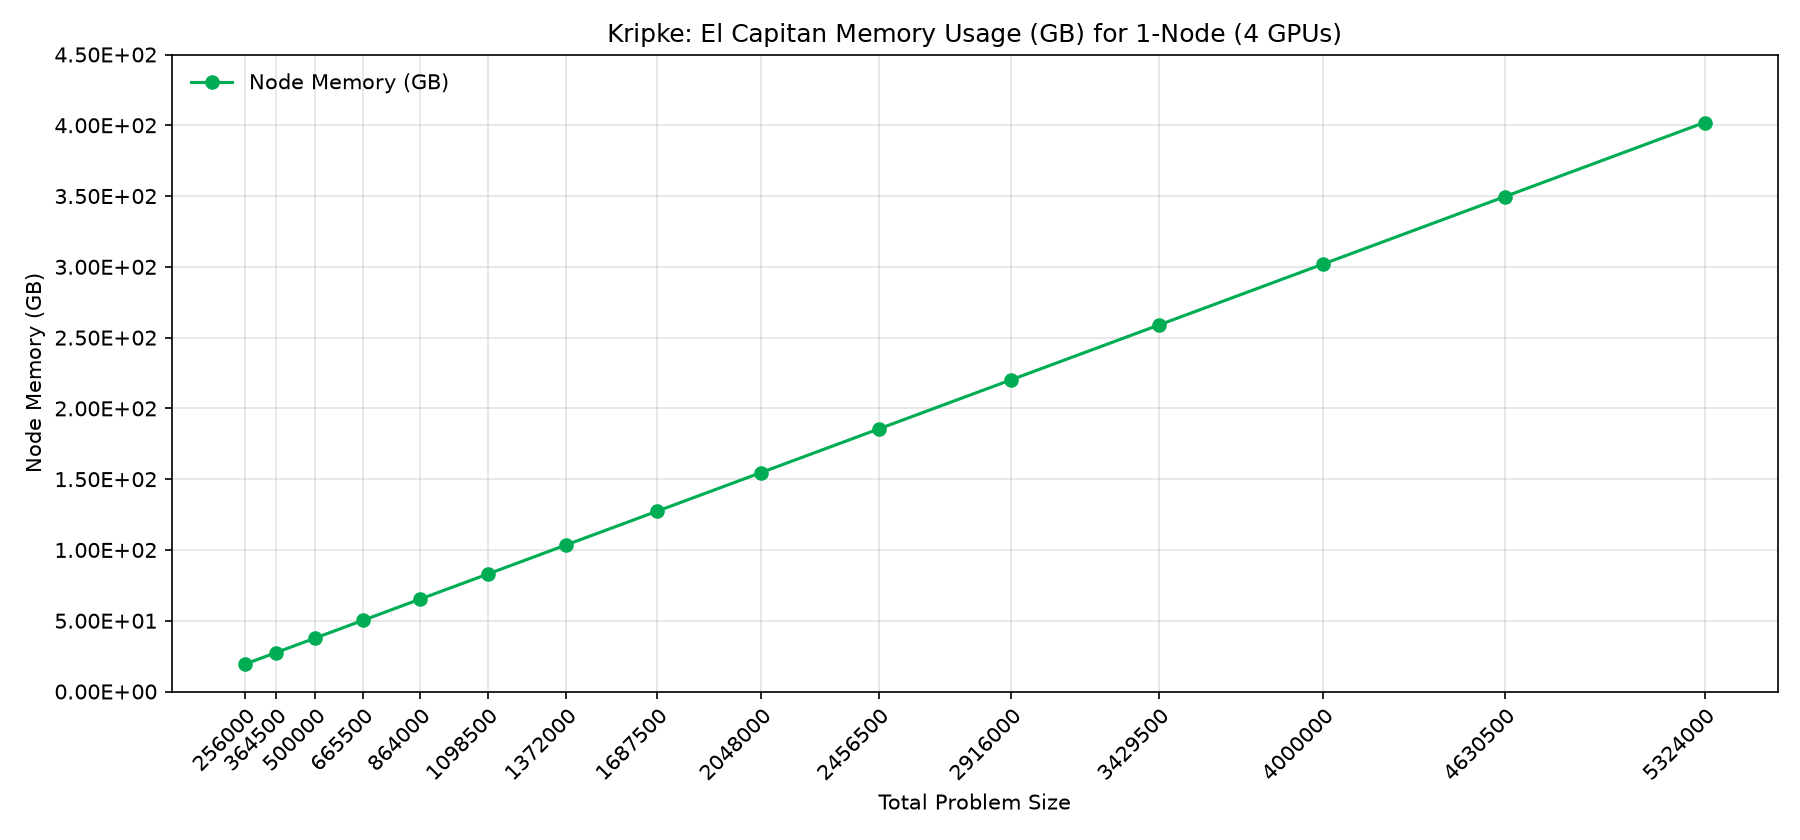
The output log reports the memory used by each Kripke data array, the total memory used, and the per-rank high-water mark of the Umpire device-memory pool. The table and figure below show Umpire memory usage for a single El Capitan node running four ranks (px=2, py=2, pz=1).
nzx |
nzy |
nzz |
Size |
Node Memory (GB) |
|---|---|---|---|---|
80 |
80 |
40 |
256000 |
19.32 |
90 |
90 |
45 |
364500 |
27.52 |
100 |
100 |
50 |
500000 |
37.76 |
110 |
110 |
55 |
665500 |
50.24 |
120 |
120 |
60 |
864000 |
65.24 |
130 |
130 |
65 |
1098500 |
82.92 |
140 |
140 |
70 |
1372000 |
103.60 |
150 |
150 |
75 |
1687500 |
127.40 |
160 |
160 |
80 |
2048000 |
154.64 |
170 |
170 |
85 |
2456500 |
185.48 |
180 |
180 |
90 |
2916000 |
220.16 |
190 |
190 |
95 |
3429500 |
258.92 |
200 |
200 |
100 |
4000000 |
302.00 |
210 |
210 |
105 |
4630500 |
349.60 |
220 |
220 |
110 |
5324000 |
401.96 |
2.1.9. Baseline on El Capitan
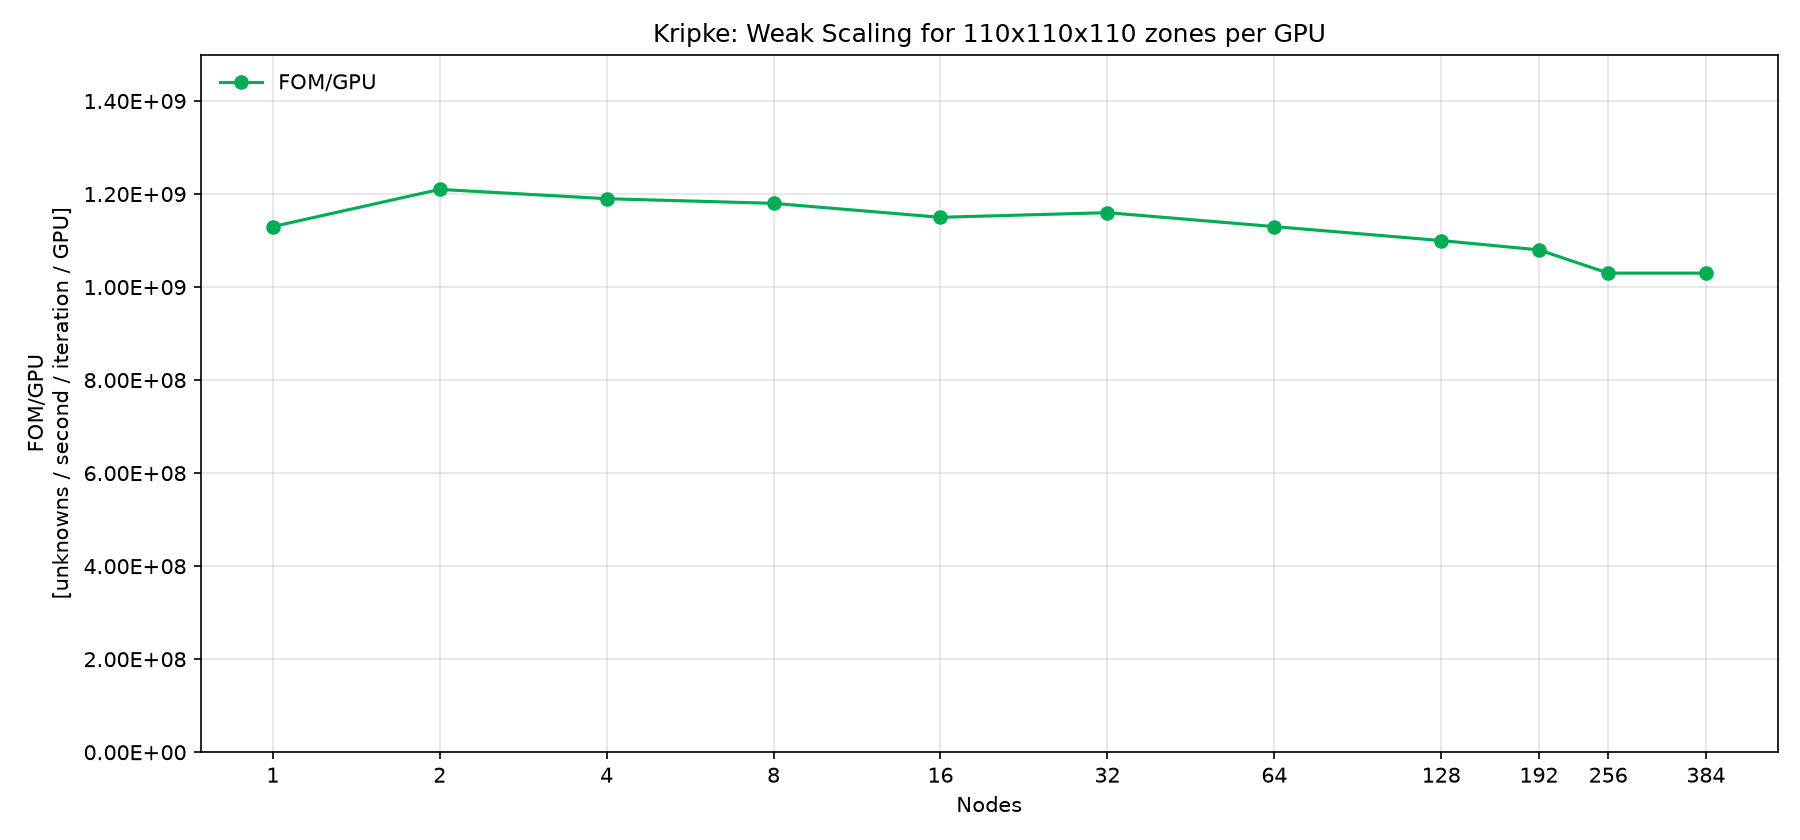
Weak scaling performance of Kripke on El Capitan (AMD Epyc + AMD MI300A) is provided as follows.
nzx |
nzy |
nzz |
px |
py |
pz |
Nodes |
GPUs |
FOM (unknowns/second/iteration) |
FOM/GPU |
|---|---|---|---|---|---|---|---|---|---|
220 |
220 |
110 |
2 |
2 |
1 |
1 |
4 |
4.52E+09 |
1.13E+09 |
220 |
220 |
220 |
2 |
2 |
2 |
2 |
8 |
9.72E+09 |
1.21E+09 |
440 |
220 |
220 |
4 |
2 |
2 |
4 |
16 |
1.90E+10 |
1.19E+09 |
440 |
440 |
220 |
4 |
4 |
2 |
8 |
32 |
3.77E+10 |
1.18E+09 |
440 |
440 |
440 |
4 |
4 |
4 |
16 |
64 |
7.35E+10 |
1.15E+09 |
880 |
440 |
440 |
8 |
4 |
4 |
32 |
128 |
1.48E+11 |
1.16E+09 |
880 |
880 |
440 |
8 |
8 |
4 |
64 |
256 |
2.89E+11 |
1.13E+09 |
880 |
880 |
880 |
8 |
8 |
8 |
128 |
512 |
5.63E+11 |
1.10E+09 |
1320 |
880 |
880 |
12 |
8 |
8 |
192 |
768 |
8.27E+11 |
1.08E+09 |
1760 |
880 |
880 |
16 |
8 |
8 |
256 |
1024 |
1.06E+12 |
1.03E+09 |
1760 |
1320 |
880 |
16 |
12 |
8 |
384 |
1536 |
1.59E+12 |
1.03E+09 |
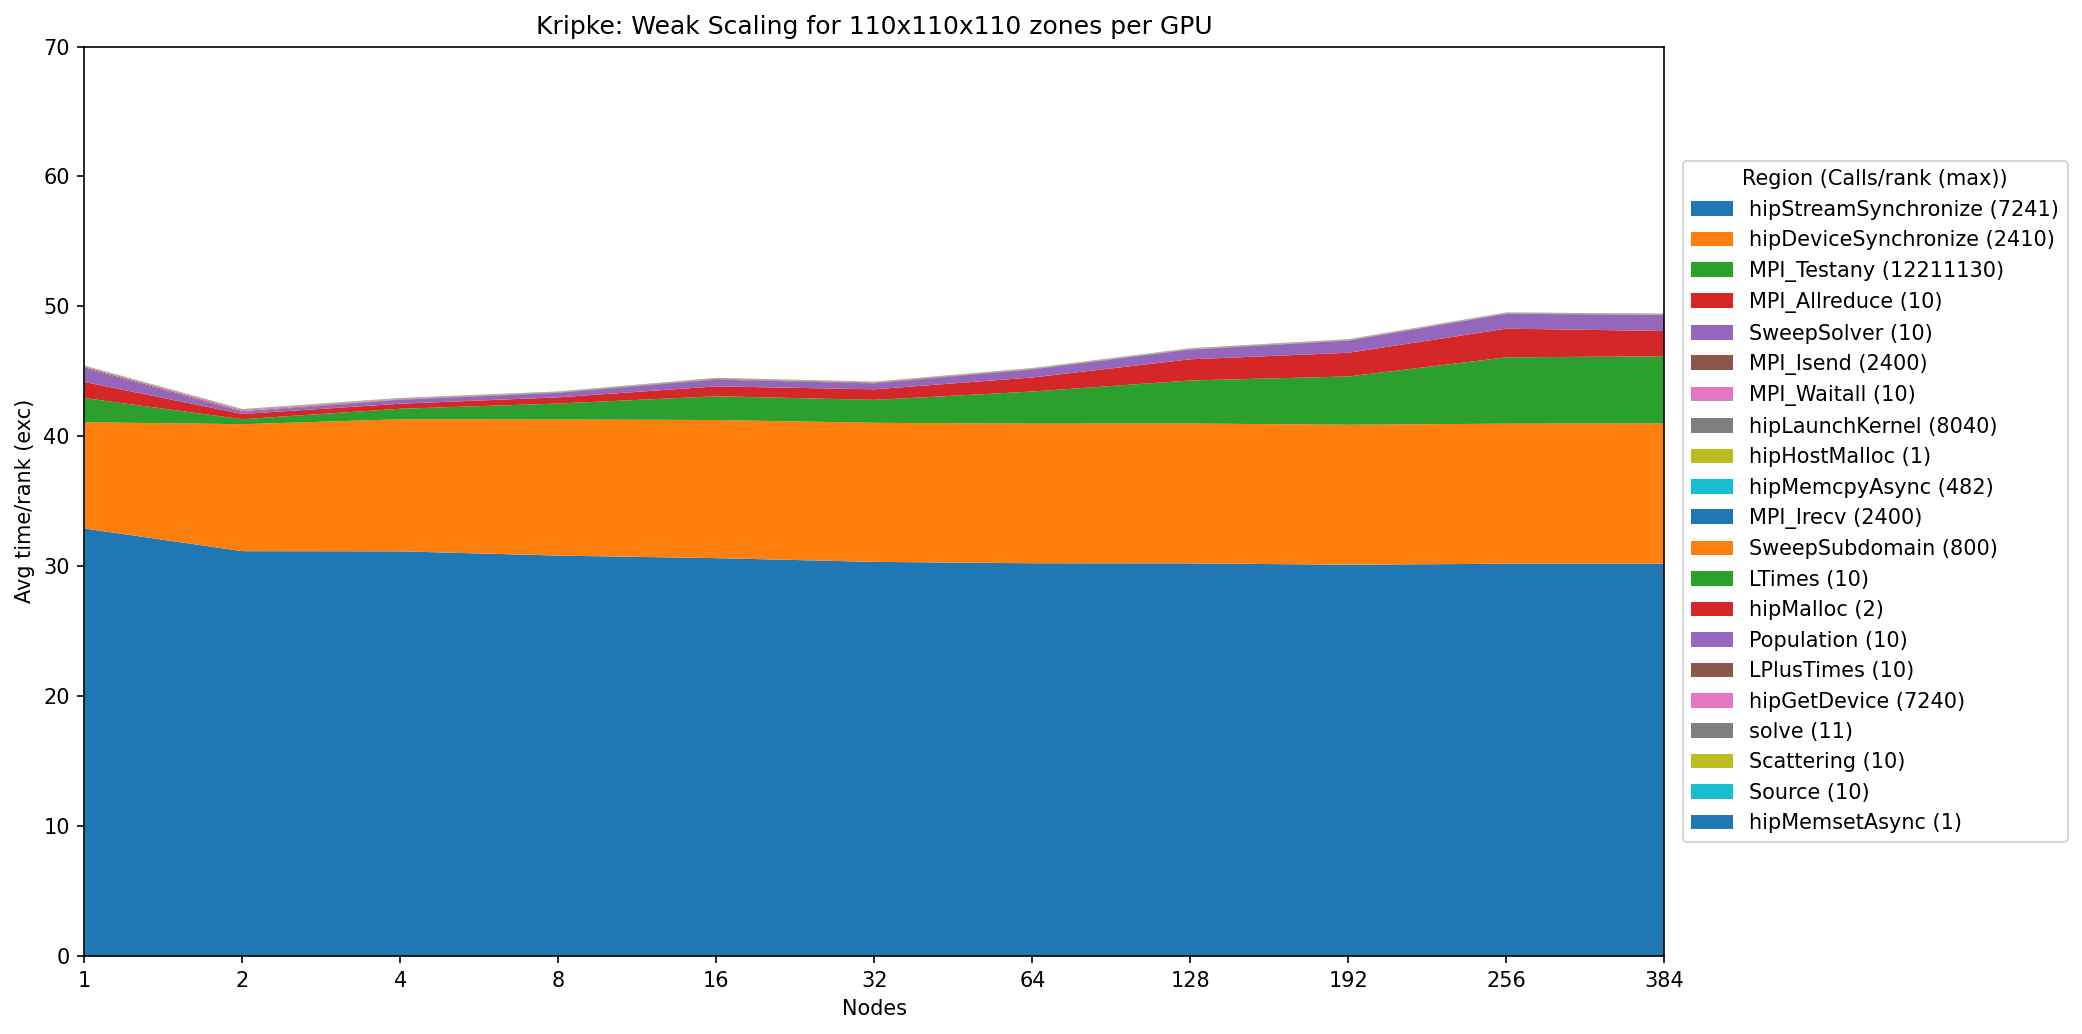
Timings were captured using Caliper and are presented below.
2.1.10. Performance Projection
The last row of Table Kripke Weak Scaling captures the baseline problem size and performance on a single Scalable Unit (SU) of El Capitan.
To project Kripke performance for a Scalable Unit (SU), scale the spatial
problem dimensions (nxx, nyy, and nzz) and the corresponding
processor decomposition (px, py, and pz) to match the size of the
SU. All other configuration options, including the number of groups, angles,
and directions, must remain unchanged. Select the spatial problem size so that
Kripke uses all available memory on each node of the SU, or as much as possible
while completing the full benchmark run successfully.
Use the El Capitan results in Memory Usage to select a problem size that meets the memory target and Baseline on El Capitan to project performance at the scale of the SU.